潘文博 Wenbo Pan
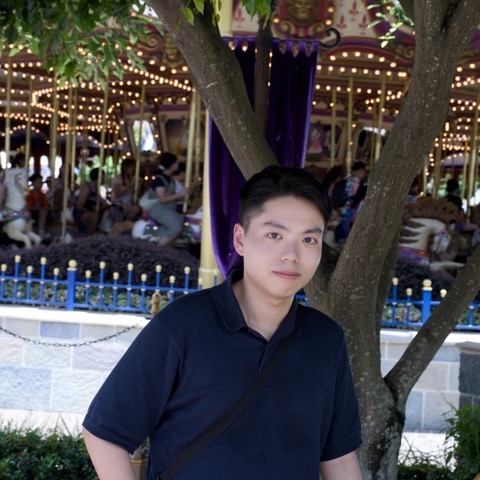
潘文博(Wenbo Pan)是香港城市大学计算机科学博士生,导师为贾小华教授。他的研究方向是理解与优化 AI agent 系统:让 agent 仅凭自己过去的无标注轨迹改进 harness(RHO,Findings of EMNLP 2026),把 agent 的记忆系统写成可执行代码并按任务演化(M*,NeurIPS 2026),以及面向推理大模型和安全对齐的可解释性方法(FlashTrace,ICML 2026 Oral;ICML 2025)。他目前是微软亚洲研究院和美团 LongCat 的研究实习生。他 2024 年本科毕业于哈尔滨工业大学英才学院。
我是香港城市大学计算机科学博士生,导师为贾小华教授。我 2024 年本科毕业于哈尔滨工业大学英才学院,此前曾与 HIT-SCIR 和 Langboat 合作。我目前是微软亚洲研究院和美团 LongCat 的研究实习生。在专注科研之前,我做过不少开源项目(moffee、Faro 系列模型以及其他工具);这些工程经验如今直接影响我构建和评估 agent 系统的方式。
我的研究兴趣是理解与优化 AI agent 系统。在优化方面,我构建能从自身无标注轨迹中改进的自我进化 agent(RHO),并把任务专属的记忆架构合成为可执行代码(M*),让 agent 的技能、工具和记忆成为它可以自行改写的组件,无需真实标签监督。在理解方面,我开发机制性工具,追踪和审查这些模型如何推理、行为从何而来:从 agent 在真实决策分岔点上的长程判断(Taste-Bench)、推理链的多 token 归因(FlashTrace),到安全对齐的几何结构(ICML 2025)。两方面相互促进:我希望优化的是行为真正可以验证的 agent。
Publications
First-author and co-first-author works are listed first, followed by collaborations. Also on .
First-author
The Tasteful Agent: Measuring and Improving Taste in Long-Horizon Tasks
Wenbo Pan, Zhichao Liu, Shujie Liu, Jingying Zeng, Chin-Yew Lin, Xianfeng Tang, Yan Lu, Qi He, Xiaohua Jia
arXiv preprint, 2026 · · · dataset
TL;DR: Taste-Bench measures whether LLM agents choose the better direction at real decision forks: on 502 questions mined from agent trajectories, the best of 14 frontier models answers only 59.7% correctly, and a larger reasoning budget does not help.
Each question freezes an engineering or research trajectory at a fork, hides everything after it, and asks the model which of two directions leads to the better outcome. Forks are mined without human annotation from parallel attempts at the same task and from detours inside one trajectory (4,657 candidates, 10.8% pass all filters). Accuracy falls as the deciding evidence moves later: the 14-model mean drops from 62.3% to 21.0%, near the 25% random score. Taste is also trainable: a student distilled from a hindsight teacher gains 17.9 points on unseen tasks, and its advice raises an executor’s success on 41 held-out SWE-bench Pro tasks from 14.6% to 33.7%. Joint work with Microsoft Research Asia.
Evolving Agents in the Dark: Retrospective Harness Optimization via Self-Preference
Wenbo Pan, Shujie Liu, Chin-Yew Lin, Jingying Zeng, Xianfeng Tang, Xiangyang Zhou, Yan Lu, Xiaohua Jia
Findings of EMNLP 2026 · ACL Anthology · · · · blog post
TL;DR: RHO improves an agent’s skills, tools, and workflows using only its own past trajectories, raising SWE-Bench Pro pass rate from 59% to 78% in one label-free optimization round.
RHO improves LLM agents without any ground-truth labels: the agent retrospectively compares its own past trajectories via self-preference, then rewrites its harness (prompts, tools, control flow) to prefer the behaviors it judges better. Under a matched budget it also beats a validation-feedback optimizer (78% vs 62%) without touching labels. Accepted to Findings of EMNLP 2026 (14.3% of 17,669 submissions). Joint work with Microsoft Research Asia.
M*: Every Task Deserves Its Own Memory Harness
Wenbo Pan, Shujie Liu, Xiangyang Zhou, Shiwei Zhang, Wanlu Shi, Mirror Xu, Xiaohua Jia
NeurIPS 2026 · · ·
TL;DR: M* represents an agent’s memory system as an executable Python program and evolves it per task, beating nine fixed-memory baselines on 7 of 8 metrics with relative gains up to 31%.
Instead of one fixed memory design for all tasks, M* searches for a task-specific memory architecture expressed as executable Python code (data schema, storage logic, and workflow instructions), optimizing how an agent stores, retrieves, and consolidates information for each workload across conversation, embodied planning, and expert reasoning benchmarks.
Towards Long-Horizon Interpretability: Efficient and Faithful Multi-Token Attribution for Reasoning LLMs
Wenbo Pan, Zhichao Liu, Xianlong Wang, Haining Yu, Xiaohua Jia
ICML 2026 (Oral) · PMLR · · · live demo
TL;DR: FlashTrace computes multi-token attribution for reasoning LLMs in a single O(N) pass, over 130x faster than the most efficient baseline (20 seconds vs 38 minutes on 5k-token spans) with higher faithfulness.
FlashTrace attributes multi-token spans in long reasoning chains to their input causes, recursively tracing importance through the chain to recover faithfulness lost when reasoning tokens absorb over 90% of attribution mass. Selected for an oral presentation at ICML 2026 (168 of 23,918 submissions, top 0.7%). Ships as a Python package with CLI and interactive HTML traces.
Can LLMs Refuse Questions They Do Not Know? Measuring Knowledge-Aware Refusal in Factual Tasks
Wenbo Pan, Jie Xu, Qiguang Chen, Junhao Dong, Libo Qin, Xinfeng Li, Haining Yu, Xiaohua Jia
ICLR 2026 ·
TL;DR: Proposes the Refusal Index, the Spearman correlation between a model’s refusal and error probabilities; it is about 70% less variable than heuristic refusal metrics, and accuracy barely predicts refusal (R² = 0.242).
Proposes knowledge-aware refusal metrics that separate “refusing because the model does not know” from blanket refusal behavior, and measures this ability across model families on factual tasks.
The Hidden Dimensions of LLM Alignment: A Multi-Dimensional Analysis of Orthogonal Safety Directions
Wenbo Pan, Zhichao Liu, Qiguang Chen, Xiangyang Zhou, Haining Yu, Xiaohua Jia
ICML 2025 · PMLR · ·
TL;DR: LLM safety alignment is controlled by multiple orthogonal activation directions: ablating the dominant one eliminates refusal entirely, and a trigger-removal attack keeps about 40% success while other jailbreaks drop to near zero.
Shows that safety alignment writes not one but many orthogonal directions into activation space. We extract this safety residual space, identify directions predictive of refusal (including interpretable secondary features such as role-playing), and show how individual directions can be ablated or steered.
Breaking Language Barriers: Cross-Lingual Continual Pre-Training at Scale
Wenzhen Zheng*, Wenbo Pan*, Xu Xu*, Libo Qin, Li Yue, Ming Zhou (co-first author)
EMNLP 2024 ·
TL;DR: Cross-lingual continual pre-training follows an extended Chinchilla scaling law, matching from-scratch loss with 25-50% fewer training FLOPs across 40 model sizes up to 5B parameters.
A scaling law for continual pre-training: given a compute budget, predicts the loss reachable when adapting an existing checkpoint to a new data distribution (e.g., a new language), validated across 40 model sizes from 40M to 5B parameters. Replaying 10-30% source-language data prevents catastrophic forgetting. Cited 25 times.
A Preliminary Evaluation of ChatGPT for Zero-shot Dialogue Understanding
Wenbo Pan, Qiguang Chen, Xiao Xu, Wanxiang Che, Libo Qin
arXiv preprint, 2023 ·
TL;DR: Zero-shot ChatGPT reaches 60.28 JGA on MultiWOZ 2.1 dialogue state tracking, nearly double GPT-3.5’s 32.25 and within one point of the fine-tuned state of the art (61.02).
One of the earliest systematic evaluations of ChatGPT on dialogue understanding (slot filling, intent detection, DST), documenting failure modes that shaped later instruction-tuning work. Cited 76 times.
Collaborations
When Does Training Data Matter? Dynamic Data Attribution via Window-level Influence Estimation
Jie Xu, Zihan Wu, Wenbo Pan, Yulong Ming, Xiaohua Jia
EMNLP 2026 · paper
TL;DR: The Window-level Influence Estimator (WIE) measures a training point’s contribution over any chosen training window instead of one static score, revealing four influence patterns and reaching 70% recall for mislabeled data on ViT-EMNIST while inspecting up to 7.5x fewer candidates than TracIn.
OrcaJack: Hijacking Agent Orchestration in Open Multi-Agent Systems
Xiang Li, Haining Yu, Wenbo Pan, Hongli Zhang, Xiaohua Jia
Findings of EMNLP 2026 · paper
TL;DR: OrcaJack forges an adversarial agent profile with a domain-skill-driven genetic algorithm so that an A2A orchestrator routes a target domain’s queries to a malicious agent, reaching up to 100% routing rate while simple pool-side defenses fail to flag the profile.
JailFlowEval: A Workflow-Safety Benchmark for LLM-Driven Enterprise Service Workflows
Zhichao Liu, Haining Yu, Wenbo Pan, Xiang Li, Wenting Zhang, Bingxuan Wang
Service Oriented Computing and Applications (SOCA), 2026 · paper
TL;DR: JailFlowEval turns harmful intents into 744 stage-specific workflow records across plan, exec, review, and improve contexts; tests on 10 models show that workflow-aware subtasks reveal unsafe continuation risks missed by prompt-level evaluation.
WebTrap: Stealthy Mid-Task Hijacking of Browser Agents During Navigation
Zhichao Liu, Wenbo Pan, Haining Yu, Ge Gao, Tianqing Zhu, Xiaohua Jia
arXiv preprint, 2026 ·
TL;DR: WebTrap injects an attacker goal into a browser agent’s task as a seamless workflow step, reaching 91.67% attack success while preserving 91.67% task utility and resisting standard defenses.
Image-to-Video Diffusion: From Foundations to Open Frontiers
Xianlong Wang, Wenbo Pan, Shijia Zhou, Ke Li, Yuqi Wang, Zeyu Ye, Hangtao Zhang, Leo Yu Zhang, Xiaohua Jia
arXiv preprint, 2026 ·
TL;DR: A survey of diffusion-based image-to-video generation: a taxonomy over architectures and training paradigms, four core design dimensions from condition encoding to spatial-temporal upsampling, and 190 references.
Dual-branch Robust Unlearnable Examples
Xianlong Wang, Hangtao Zhang, Wenbo Pan, Ziqi Zhou, Changsong Jiang, Li Zeng, Xiaohua Jia
ICML 2026 ·
TL;DR: DUNE optimizes dual-branch unlearnable perturbations in the spatial and color domains, outperforming 12 state-of-the-art schemes under 7 defenses and capping CIFAR-10 test accuracy at 14.95-50.82%.
LMCleaner: Efficient and Certified Online Unlearning via Influence Propagation Truncation
Jie Xu, Zihan Wu, Wenbo Pan, Jiao Yin, Yong-Feng Ge, Hua Wang, Cong Wang, Xiaohua Jia
ICML 2026 · paper
TL;DR: LMCleaner handles unlearning requests at any step of ongoing training by truncating influence propagation to a window and masking the residual with subspace-aware noise, making the model (ε, δ)-indistinguishable from retraining with over 100x computational savings over baselines.
Tug-of-War No More: Harmonizing Accuracy and Robustness in Vision-Language Models via Stability-Aware Task Vector Merging
Junhao Dong, Xinghua Qu, Cong Zhang, Qi Rong Sua, Nguyen Duc Thai, Wenbo Pan, Xinfeng Li, Tongliang Liu, Piotr Koniusz, Yew-Soon Ong
ICLR 2026 · paper
TL;DR: Stability-aware merging composes task vectors from naturally and adversarially fine-tuned VLMs, keeping parameters that stay stable under both objectives and suppressing conflicting ones, which yields better clean-robust trade-offs than naive merging without any retraining.
Improve Fluency of Neural Machine Translation Using Large Language Models
Jianfei He, Wenbo Pan, Jijia Yang, Sen Peng, Xiaohua Jia
MT Summit 2025
TL;DR: Integrating a Llama2-13B fluency signal into NMT training via contrastive fluency enhancement raises BLEU on all three WMT pairs (up to +1.09), where LLM re-ranking and refinement fail.
End-to-end Task-oriented Dialogue: A Survey of Tasks, Methods, and Future Directions
Libo Qin, Wenbo Pan, Qiguang Chen, Lizi Liao, Zhou Yu, Yue Zhang, Wanxiang Che, Min Li
EMNLP 2023 ·
TL;DR: The first survey of end-to-end task-oriented dialogue: a Modularly vs. Fully EToD taxonomy with curated leaderboards covering 39 models across 4 benchmarks at etods.net. Cited 82 times.
Blog
- Oct 16, 2026 Claude 最全防封指北 中文
- Jun 12, 2026 I Built a Self-Improving Dynamic Workflow, and Wrote a Paper to Measure It
- Jun 12, 2026 Taste Is the Next Capability AI Will Crack
- Jun 12, 2026 我做了个自我优化的 Dynamic Workflow,还写了篇 Paper 测量它的效果 中文
- Jun 12, 2026 Taste 是下一个被 AI 攻克的能力 中文
- Nov 5, 2025 Persistent VSCode Remote Terminals with tmux
- Nov 5, 2025 再也不担心连接中断!一行配置让 VSCode 远程终端持久化 中文
- Mar 20, 2025 Digital Productivity Setup in 2025
- Mar 20, 2025 My Reading List
- Mar 20, 2025 我在 2025 年的数字生产力工具 中文
- Mar 20, 2025 我的推荐书籍 中文
- Sep 20, 2024 Recreating o1 at Home with Role-Play LLMs
- Sep 20, 2024 利用 Role-Play LLM 复现 o1 推理性能 中文
- May 20, 2024 关于长文本精调的一切 中文
- May 10, 2024 Everything About Long Context Fine-tuning
- Apr 7, 2024 What I Think About When I Edit
- Apr 7, 2024 如何让你的英文写作更流畅 中文
- Aug 3, 2021 Why Momentum Really Works
- Aug 3, 2021 为何我们需要动量 中文